BOSS#
- class pyts.transformation.BOSS(word_size: int = 4, n_bins: int = 4, strategy: str = 'quantile', window_size: int | float = 10, window_step: int | float = 1, anova: bool = False, drop_sum: bool = False, norm_mean: bool = False, norm_std: bool = False, numerosity_reduction: bool = True, sparse: bool = True, alphabet: ArrayLike | None = None)[source]#
Bag of Symbolic Fourier Approximation Symbols.
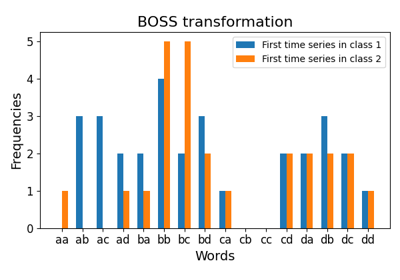
For each time series, subseries are extracted using a sliding window. Then the subseries are transformed into a word using the Symbolic Fourier Approximation (SFA) algorithm. For each time series, the words are grouped together and a histogram counting the occurences of each word is created.
- Parameters:
- word_sizeint (default = 4)
Size of each word.
- n_binsint (default = 4)
The number of bins to produce. It must be between 2 and 26.
- strategystr (default = ‘quantile’)
Strategy used to define the widths of the bins:
‘uniform’: All bins in each sample have identical widths
‘quantile’: All bins in each sample have the same number of points
‘normal’: Bin edges are quantiles from a standard normal distribution
‘entropy’: Bin edges are computed using information gain
- window_sizeint or float (default = 10)
Size of the sliding window. If float, it represents the percentage of the size of each time series and must be between 0 and 1. The window size will be computed as
ceil(window_size * n_timestamps).- window_stepint or float (default = 1)
Step of the sliding window. If float, it represents the percentage of the size of each time series and must be between 0 and 1. The window size will be computed as
ceil(window_step * n_timestamps).- anovabool (default = False)
If True, the Fourier coefficient selection is done via a one-way ANOVA test. If False, the first Fourier coefficients are selected.
- drop_sumbool (default = False)
If True, the first Fourier coefficient (i.e. the sum of the subseries) is dropped. Otherwise, it is kept.
- norm_meanbool (default = False)
If True, center each subseries before scaling.
- norm_stdbool (default = False)
If True, scale each subseries to unit variance.
- numerosity_reductionbool (default = True)
If True, delete sample-wise all but one occurence of back to back identical occurences of the same words.
- sparsebool (default = True)
Return a sparse matrix if True, else return an array.
- alphabetNone or array-like, shape = (n_bins,)
Alphabet to use. If None, the first n_bins letters of the Latin alphabet are used.
- Attributes:
- vocabulary_dict
A mapping of feature indices to terms.
References
[1]P. Schäfer, “The BOSS is concerned with time series classification in the presence of noise”. Data Mining and Knowledge Discovery, 29(6), 1505-1530 (2015).
Examples
>>> from pyts.datasets import load_gunpoint
>>> from pyts.transformation import BOSS
>>> X_train, X_test, _, _ = load_gunpoint(return_X_y=True)
>>> boss = BOSS(word_size=2, n_bins=2, sparse=False)
>>> boss.fit(X_train)
BOSS(...)
>>> sorted(boss.vocabulary_.values())
['aa', 'ab', 'ba', 'bb']
>>> boss.transform(X_test)
array(...)
Methods
__init__([word_size, n_bins, strategy, ...])fit(X[, y])Fit the model according to the given training data.
fit_transform(X[, y])Fit the data then transform it.
get_metadata_routing()Get metadata routing of this object.
get_params([deep])Get parameters for this estimator.
set_params(**params)Set the parameters of this estimator.
transform(X)Transform the provided data.
- __init__(word_size: int = 4, n_bins: int = 4, strategy: str = 'quantile', window_size: int | float = 10, window_step: int | float = 1, anova: bool = False, drop_sum: bool = False, norm_mean: bool = False, norm_std: bool = False, numerosity_reduction: bool = True, sparse: bool = True, alphabet: ArrayLike | None = None) None[source]#
- fit(X: ArrayLike, y: ArrayLike | None = None) Self[source]#
Fit the model according to the given training data.
- Parameters:
- Xarray-like, shape = (n_samples, n_timestamps)
Training vector.
- yNone or array-like, shape = (n_samples,)
Class labels for each data sample.
- Returns:
- selfobject
- fit_transform(X: ArrayLike, y: ArrayLike | None = None) NDArray[int64] | csr_matrix[source]#
Fit the data then transform it.
- Parameters:
- Xarray-like, shape = (n_samples, n_timestamps)
Training vector.
- yNone or array-like, shape = (n_samples,)
Class labels for each data sample.
- Returns:
- X_newsparse matrix, shape = (n_samples, n_words)
Document-term matrix.
- transform(X: ArrayLike) NDArray[int64] | csr_matrix[source]#
Transform the provided data.
- Parameters:
- Xarray-like, shape = (n_samples, n_timestamps)
Test samples.
- Returns:
- X_newsparse matrix, shape = (n_samples, n_words)
Document-term matrix.