SymbolicAggregateApproximation#
- class pyts.approximation.SymbolicAggregateApproximation(n_bins: int = 4, strategy: str = 'quantile', raise_warning: bool = True, alphabet: str | ArrayLike | None = None)[source]#
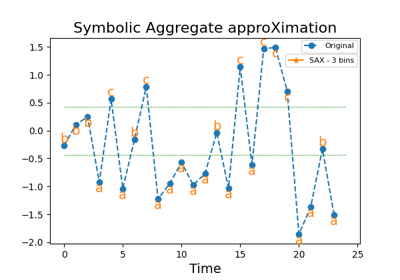
Symbolic Aggregate approXimation.
- Parameters:
- n_binsint (default = 4)
The number of bins to produce. It must be between 2 and
min(n_timestamps, 26).- strategy‘uniform’, ‘quantile’ or ‘normal’ (default = ‘quantile’)
Strategy used to define the widths of the bins:
‘uniform’: All bins in each sample have identical widths
‘quantile’: All bins in each sample have the same number of points
‘normal’: Bin edges are quantiles from a standard normal distribution
- raise_warningbool (default = True)
If True, a warning is raised when the number of bins is smaller for at least one sample. In this case, you should consider decreasing the number of bins or removing these samples.
- alphabetNone, ‘ordinal’ or array-like, shape = (n_bins,)
Alphabet to use. If None, the first n_bins letters of the Latin alphabet are used. If ‘ordinal’, integers are used.
References
[1]J. Lin, E. Keogh, L. Wei, and S. Lonardi, “Experiencing SAX: a novel symbolic representation of time series”. Data Mining and Knowledge Discovery, 15(2), 107-144 (2007).
Examples
>>> from pyts.approximation import SymbolicAggregateApproximation
>>> X = [[0, 4, 2, 1, 7, 6, 3, 5],
...      [2, 5, 4, 5, 3, 4, 2, 3]]
>>> transformer = SymbolicAggregateApproximation()
>>> print(transformer.transform(X))
[['a' 'c' 'b' 'a' 'd' 'd' 'b' 'c']
 ['a' 'd' 'c' 'd' 'b' 'c' 'a' 'b']]
Methods
__init__([n_bins, strategy, raise_warning, ...])fit([X, y])Pass.
fit_transform(X[, y])Fit to data, then transform it.
get_metadata_routing()Get metadata routing of this object.
get_params([deep])Get parameters for this estimator.
set_params(**params)Set the parameters of this estimator.
transform(X)Bin the data with the given alphabet.
- __init__(n_bins: int = 4, strategy: str = 'quantile', raise_warning: bool = True, alphabet: str | ArrayLike | None = None) None[source]#