MultipleCoefficientBinning#
- class pyts.approximation.MultipleCoefficientBinning(n_bins: int = 4, strategy: str = 'quantile', alphabet: str | ArrayLike | None = None)[source]#
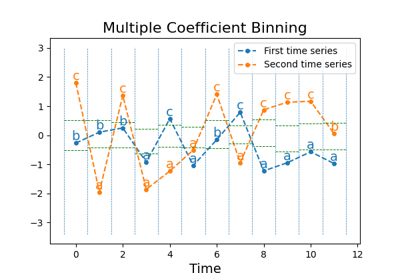
Bin continuous data into intervals column-wise.
- Parameters:
- n_binsint (default = 4)
The number of bins to produce. It must be between 2 and
min(n_samples, 26).- strategystr (default = ‘quantile’)
Strategy used to define the widths of the bins:
‘uniform’: All bins in each sample have identical widths
‘quantile’: All bins in each sample have the same number of points
‘normal’: Bin edges are quantiles from a standard normal distribution
‘entropy’: Bin edges are computed using information gain
- alphabetNone, ‘ordinal’ or array-like, shape = (n_bins,)
Alphabet to use. If None, the first n_bins letters of the Latin alphabet are used if n_bins is lower than 27, otherwise the alphabet will be defined to [chr(i) for i in range(n_bins)]. If ‘ordinal’, integers are used.
- Attributes:
- bin_edges_array, shape = (n_bins - 1,) or (n_timestamps, n_bins - 1)
Bin edges with shape = (n_bins - 1,) if
strategy='normal'or (n_timestamps, n_bins - 1) otherwise.
References
[1]P. Schäfer, and M. Högqvist, “SFA: A Symbolic Fourier Approximation and Index for Similarity Search in High Dimensional Datasets”, International Conference on Extending Database Technology, 15, 516-527 (2012).
Examples
>>> from pyts.approximation import MultipleCoefficientBinning
>>> X = [[0, 4],
...      [2, 7],
...      [1, 6],
...      [3, 5]]
>>> transformer = MultipleCoefficientBinning(n_bins=2)
>>> print(transformer.fit_transform(X))
[['a' 'a']
 ['b' 'b']
 ['a' 'b']
 ['b' 'a']]
Methods
__init__([n_bins, strategy, alphabet])fit(X[, y])Compute the bin edges for each feature.
fit_transform(X[, y])Fit to data, then transform it.
get_metadata_routing()Get metadata routing of this object.
get_params([deep])Get parameters for this estimator.
set_params(**params)Set the parameters of this estimator.
transform(X)Bin the data.
- __init__(n_bins: int = 4, strategy: str = 'quantile', alphabet: str | ArrayLike | None = None) None[source]#