BOSSVS#
- class pyts.classification.BOSSVS(word_size: int = 4, n_bins: int = 4, window_size: int | float = 10, window_step: int | float = 1, anova: bool = False, drop_sum: bool = False, norm_mean: bool = False, norm_std: bool = False, strategy: str = 'quantile', alphabet: str | ArrayLike | None = None, numerosity_reduction: bool = True, use_idf: bool = True, smooth_idf: bool = False, sublinear_tf: bool = True)[source]#
Bag-of-SFA Symbols in Vector Space.
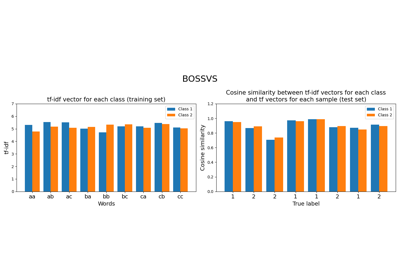
Each time series is transformed into an histogram using the Bag-of-SFA Symbols (BOSS) algorithm. Then, for each class, the histograms are added up and a tf-idf vector is computed. The predicted class for a new sample is the class giving the highest cosine similarity between its tf vector and the tf-idf vectors of each class.
- Parameters:
- word_sizeint (default = 4)
Size of each word.
- n_binsint (default = 4)
The number of bins to produce. It must be between 2 and 26.
- window_sizeint or float (default = 10)
Size of the sliding window. If float, it represents the percentage of the size of each time series and must be between 0 and 1. The window size will be computed as
ceil(window_size * n_timestamps).- window_stepint or float (default = 1)
Step of the sliding window. If float, it represents the percentage of the size of each time series and must be between 0 and 1. The window size will be computed as
ceil(window_step * n_timestamps).- anovabool (default = False)
If True, the Fourier coefficient selection is done via a one-way ANOVA test. If False, the first Fourier coefficients are selected.
- drop_sumbool (default = False)
If True, the first Fourier coefficient (i.e. the sum of the subseries) is dropped. Otherwise, it is kept.
- norm_meanbool (default = False)
If True, center each subseries before scaling.
- norm_stdbool (default = False)
If True, scale each subseries to unit variance.
- strategystr (default = ‘quantile’)
Strategy used to define the widths of the bins:
‘uniform’: All bins in each sample have identical widths
‘quantile’: All bins in each sample have the same number of points
‘normal’: Bin edges are quantiles from a standard normal distribution
‘entropy’: Bin edges are computed using information gain
- alphabetNone, ‘ordinal’ or array-like, shape = (n_bins,)
Alphabet to use. If None, the first n_bins letters of the Latin alphabet are used.
- numerosity_reductionbool (default = True)
If True, delete sample-wise all but one occurence of back to back identical occurences of the same words.
- use_idfbool (default = True)
Enable inverse-document-frequency reweighting.
- smooth_idfbool (default = False)
Smooth idf weights by adding one to document frequencies, as if an extra document was seen containing every term in the collection exactly once. Prevents zero divisions.
- sublinear_tfbool (default = True)
Apply sublinear tf scaling, i.e. replace tf with 1 + log(tf).
- Attributes:
- classes_array, shape = (n_classes,)
An array of class labels known to the classifier.
- idf_array, shape = (n_features,) , or None
The learned idf vector (global term weights) when
use_idf=True, None otherwise.- tfidf_array, shape = (n_classes, n_words)
Term-document matrix.
- vocabulary_dict
A mapping of feature indices to terms.
References
[1]P. Schäfer, “Scalable Time Series Classification”. Data Mining and Knowledge Discovery, 30(5), 1273-1298 (2016).
Examples
>>> from pyts.classification import BOSSVS
>>> from pyts.datasets import load_gunpoint
>>> X_train, X_test, y_train, y_test = load_gunpoint(return_X_y=True)
>>> clf = BOSSVS(window_size=28)
>>> clf.fit(X_train, y_train)
BOSSVS(...)
>>> clf.score(X_test, y_test)
0.98
Methods
__init__([word_size, n_bins, window_size, ...])Evaluate the cosine similarity between document-term matrix and X.
fit(X, y)Compute the document-term matrix.
get_metadata_routing()Get metadata routing of this object.
get_params([deep])Get parameters for this estimator.
predict(X)Predict the class labels for the provided data.
score(X, y[, sample_weight])Return the mean accuracy on the given test data and labels.
set_params(**params)Set the parameters of this estimator.
set_score_request(*[, sample_weight])Configure whether metadata should be requested to be passed to the
scoremethod.- __init__(word_size: int = 4, n_bins: int = 4, window_size: int | float = 10, window_step: int | float = 1, anova: bool = False, drop_sum: bool = False, norm_mean: bool = False, norm_std: bool = False, strategy: str = 'quantile', alphabet: str | ArrayLike | None = None, numerosity_reduction: bool = True, use_idf: bool = True, smooth_idf: bool = False, sublinear_tf: bool = True) None[source]#
- decision_function(X: ArrayLike) NDArray[float64][source]#
Evaluate the cosine similarity between document-term matrix and X.
- Parameters:
- Xarray-like, shape (n_samples, n_timestamps)
Test samples.
- Returns:
- Xarray, shape (n_samples, n_classes)
Cosine similarity between the document-term matrix and X.
- fit(X: ArrayLike, y: ArrayLike) Self[source]#
Compute the document-term matrix.
- Parameters:
- Xarray-like, shape = (n_samples, n_timestamps)
Training vector.
- yarray-like, shape = (n_samples,)
Class labels for each data sample.
- Returns:
- selfobject
- predict(X: ArrayLike) NDArray[Any][source]#
Predict the class labels for the provided data.
- Parameters:
- Xarray-like, shape = (n_samples, n_timestamps)
Test samples.
- Returns:
- y_predarray, shape = (n_samples,)
Class labels for each data sample.
- set_score_request(*, sample_weight: bool | None | str = '$UNCHANGED$') BOSSVS#
Configure whether metadata should be requested to be passed to the
scoremethod.Note that this method is only relevant when this estimator is used as a sub-estimator within a meta-estimator and metadata routing is enabled with
enable_metadata_routing=True(seesklearn.set_config()). Please check the User Guide on how the routing mechanism works.The options for each parameter are:
True: metadata is requested, and passed toscoreif provided. The request is ignored if metadata is not provided.False: metadata is not requested and the meta-estimator will not pass it toscore.None: metadata is not requested, and the meta-estimator will raise an error if the user provides it.str: metadata should be passed to the meta-estimator with this given alias instead of the original name.
The default (
sklearn.utils.metadata_routing.UNCHANGED) retains the existing request. This allows you to change the request for some parameters and not others.Added in version 1.3.
- Parameters:
- sample_weightstr, True, False, or None, default=sklearn.utils.metadata_routing.UNCHANGED
Metadata routing for
sample_weightparameter inscore.
- Returns:
- selfobject
The updated object.