WordExtractor#
- class pyts.bag_of_words.WordExtractor(window_size: int | float = 0.1, window_step: int | float = 1, numerosity_reduction: bool = True)[source]#
Transform discretized time series into sequences of words.
- Parameters:
- window_sizeint or float (default = 0.1)
Size of the sliding window (i.e. the size of each word). If float, it represents the percentage of the size of each time series and must be between 0 and 1. The window size will be computed as
ceil(window_size * n_timestamps).- window_stepint or float (default = 1)
Step of the sliding window. If float, it represents the percentage of the size of each time series and must be between 0 and 1. The window size will be computed as
ceil(window_step * n_timestamps).- numerosity_reductionbool (default = True)
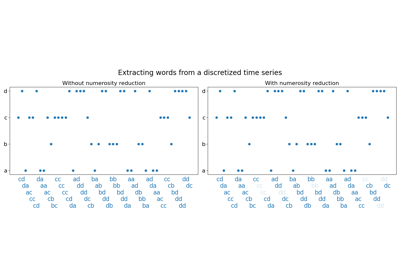
If True, delete sample-wise all but one occurence of back to back identical occurences of the same words.
Examples
>>> from pyts.bag_of_words import WordExtractor
>>> X = [['a', 'a', 'b', 'a', 'b', 'b', 'b', 'b', 'a'],
...      ['a', 'b', 'c', 'c', 'c', 'c', 'a', 'a', 'c']]
>>> word = WordExtractor(window_size=2)
>>> print(word.transform(X))
['aa ab ba ab bb ba' 'ab bc cc ca aa ac']
>>> word = WordExtractor(window_size=2, numerosity_reduction=False)
>>> print(word.transform(X))
['aa ab ba ab bb bb bb ba' 'ab bc cc cc cc ca aa ac']
Methods
__init__([window_size, window_step, ...])fit([X, y])Pass.
fit_transform(X[, y])Fit to data, then transform it.
get_metadata_routing()Get metadata routing of this object.
get_params([deep])Get parameters for this estimator.
set_params(**params)Set the parameters of this estimator.
transform(X)Transform time series into sequences of words.
- __init__(window_size: int | float = 0.1, window_step: int | float = 1, numerosity_reduction: bool = True) None[source]#